Answer Capsules: How to Structure Content So AI Can Cite It
 Lourdes 12 min read
TL;DR-Answer Capsules are content fragments structured into four components (direct answer, evidence, scope, and qualifier) designed TL;DR-to be extracted by RAG systems. In B2B, where organic traffic justifies budget and sales cycles are long, this content architecture is not tactical, it is operational. The article explains how to build extractable capsules, inject proprietary data to avoid AI Slop, implement mandatory technical infrastructure such as llms.txt and Schema Markup, apply the framework to transactional pages to generate MQLs, and measure the Share of Voice in LLMs to justify pipeline impact when traditional attribution fails.
What is an Answer Capsule and why does it work in RAG architectures?
An Answer Capsule is a content fragment structured into four components: direct answer, quantifiable evidence, scope of validity, and technical qualifier. Its purpose is for a RAG model to identify it as a citation candidate without requiring content reformulation. It is not a summary; it is a minimal unit of information ready for extraction.
Current LLMs operate on semantic embeddings and retrieve blocks that maximize relevance and precision. If a fragment contains ambiguity, fuzzy context, or lacks an explicit source, the model discards it. This is why capsules always include a qualifier. It is not enough to simply state that a tactic works; one must specify under what conditions, with what type of product, and in which segment. This reduces the fragment's entropy and increases the probability of extraction.
Example of a poorly structured capsule: Native integrations improve conversion in SaaS tools because they reduce technical friction. This is ineffective—it lacks precision, data, and a qualifier.
Example of a well-structured capsule: Native integrations with Salesforce increase conversion by up to 34% in B2B marketing automation tools, based on implementation data from companies with more than 500 employees during 2024. This is actionable for citation.
The difference lies in information density. An LLM can validate the latter statement by cross-referencing it with its base knowledge, verifying domain consistency, and presenting it as a reliable response. The former is merely noise.
Structure of an Answer Capsule: The Four Mandatory Components
Each capsule must be readable independently. It cannot depend on the previous paragraph or the general context of the article. This means that each block must function as a complete micro-response.
The first component is the direct answer. A declarative sentence of a maximum of 150 characters that answers a specific question. No subordinate clauses, no previous nuances. If the question is how long a CDP implementation in B2B takes, the answer is: A CDP implementation in B2B companies takes between 8 and 16 weeks in environments with more than three active data sources.
The second component is the evidence. It can be internal data, a reference to an external study, or a verifiable benchmark. Without this, the capsule carries no weight. AI models prioritize fragments that include numbers, ranges, percentages, or comparisons. Example: 62% of implementations that exceed 12 weeks present alignment problems between technical and marketing teams, according to an internal analysis of 47 projects in 2024.
The third component is the scope. It defines the perimeter of validity: company type, sector, team size, technological stack. This prevents the LLM from generalizing the answer to contexts where it does not apply. Example: This metric applies to B2B SaaS companies with marketing teams of more than 10 people and a stack based on HubSpot or Salesforce Marketing Cloud.
The fourth component is the qualifier. A technical caveat, a prerequisite, or an operational warning. Example: Timelines may extend if the company uses legacy CRMs without documented REST API or if it requires integration with an on-premise ERP.
These four blocks can appear in the same paragraph or be distributed across two or three consecutive sentences. The important thing is that they are present and that the fragment is extractable without loss of meaning.
Information Gain: How to inject proprietary data without falling into AI Slop
The concept of Information Gain comes from information theory. In SEO and GEO, it means providing content that does not exist in the model's training corpus. If your article repeats what is already on a thousand sites, the LLM has no incentive to cite you. It prefers the most authoritative or the most recent source. However, if you provide proprietary data, internal benchmarks, or named analysis structures, the model has no alternative. It either cites you or it cannot answer.
Proprietary data does not have to be formal studies. It can be aggregated customer metrics, tool comparisons based on real-world tests, documented implementation times, or error rates in specific integrations. What matters is that they are verifiable, contextualized, and cannot be reproduced from generic content.
A practical example: instead of writing that automation tools improve productivity, publish a table with execution times measured across five different platforms, with identical configurations, on list segmentation tasks. That is Information Gain. An LLM can cite you as a primary source because there is no other reference with that level of granularity.
The problem with AI Slop is that it dilutes the signal. When thousands of AI-generated articles repeat the same structure and the same ideas without new data, models begin to penalize those domains. It is not an explicit penalty; it is a probabilistic matter. If your content does not provide information gain, it loses ranking in the RAG retrieval graph.
To avoid this, every article must include at least one unique element: a data point not found on Wikipedia, a proprietary analysis framework that you have documented before, or a technical comparison with explicit methodology. That does not guarantee citation, but it does ensure survival in the model's semantic index.
Technical Infrastructure for GEO: llms.txt, Crawling, and Schema Markup
Content structure is useless if AI bots cannot access it. As of 2026, many B2B domains continue to block crawlers like GPTBot, ClaudeBot, or PerplexityBot in the robots.txt file, fearing that their data might train models without compensation. This is a tactical error. If you block the crawler, your content does not enter the index. If it does not enter the index, it cannot be cited. And if it cannot be cited, you lose organic traffic with no possibility of recovery.
The llms.txt standard was proposed in 2024 as a plain text file that declares which parts of the site are optimized for extraction by LLMs. It acts as a priority map. It is not mandatory, but models that implement it use it to decide which content to index first. The file must be at the root of the domain and list high-value URLs with structured metadata: title, description, update date, and key topics.
Basic example of llms.txt:
URL | Title | Date | Topics |
| Framework Answer Capsules for B2B GEO | 2025-01-15 | GEO, RAG, B2B marketing |
| CDP Implementation Guide for B2B SaaS | 2024-11-20 | CDP, integration, first-party data |
This tells the crawler that those URLs contain dense and updated content. It does not guarantee citation, but it improves the probability of deep indexing.
Schema Markup also matters. LLMs can interpret structured data in JSON-LD format. If you mark an article as Article with properties such as author, datePublished, dateModified, and citation, the model can validate the freshness of the content and the authorship. This increases trust in the source.
Basic Schema example:
Context | Type | Title | Published | Updated | Author | Citation |
Article | Framework of Answer Capsules for B2B GEO | 2025-01-15 | 2025-01-15 | Studio1 — Organization |
This is not optional; it is infrastructure. Without technical accessibility and semantic metadata, content can be excellent and remain invisible to retrieval systems.
Product-Led SEO with Answer Capsules: How to apply it to transactional pages
Answer Capsules are not just for educational content; they work best on transactional pages. This includes product comparisons, integration pages, specific use cases, and implementation guides—everything at the bottom of the funnel that generates direct MQLs.
The problem with classic transactional content is that it is written to persuade, not to be cited. Product pages have benefit blocks, testimonials, and CTAs, but they lack extractable technical fragments. An LLM cannot cite a sentence like "our software improves collaboration" because it does not provide verifiable information. However, it can cite: "Our platform reduces the synchronization time between CRM and email tools by 68% in companies with databases of over 50,000 contacts, according to measurements from 22 clients during 2024".
The tactic is to convert every product page into a hub of Answer Capsules. Instead of a single block of text, structure the information into 150-character blocks that answer specific questions: how long the integration takes, which APIs are supported, what the record limit is, what level of support each plan includes, and what technical prerequisites the implementation has.
This not only improves the probability of citation, but it also increases conversion on the site itself. Users arriving from Zero-Click searches look for quick answers. If the product page can be scanned in 15 seconds and offers precise, straightforward data, the bounce rate drops and the quality of the lead rises.
A practical example: a sales automation software company has a Salesforce integration page. Instead of a generic paragraph about connectivity, structure the content into capsules:
Average configuration time: 48 hours with sandbox access.
Supported APIs: REST, SOAP, Bulk API 2.0.
Object synchronization: Leads, Contacts, Opportunities, Custom Objects.
Prerequisites: Salesforce Enterprise Edition or higher, enabled API permissions.
Each of these capsules can be cited independently in a ChatGPT or Perplexity response.
GEO Metrics: How to measure Share of Voice in LLMs and justify pipeline impact
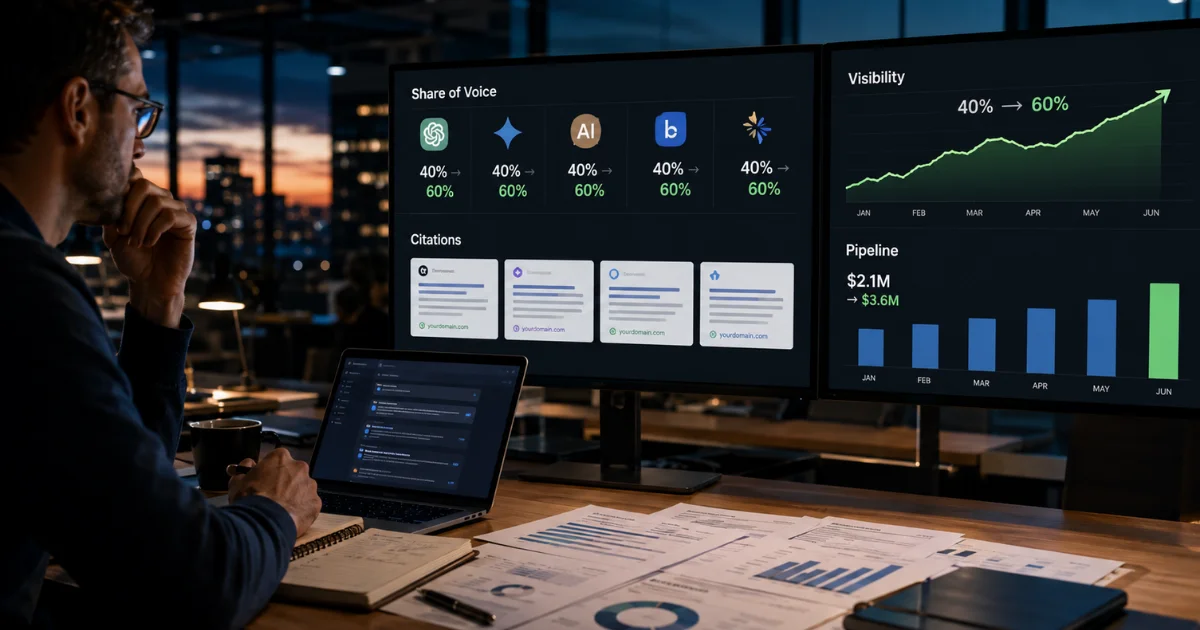
The problem with GEO is that there is no consolidated tool to measure impact. Google Search Console does not track citations in LLMs. Google Analytics does not differentiate traffic from AI Overviews. And classic attribution dashboards cannot assign pipeline to content that never generates a click.
The key metric is the Share of Voice in AI responses. This means measuring how many times your domain is cited in the responses of ChatGPT, Perplexity, Gemini, or Claude when someone asks about your product category. It is not traffic; it is pre-click visibility.
To measure it, you must build a manual or semi-automatic monitoring system. The most direct tactic is to create a corpus of 30 to 50 questions relevant to your buyer persona, run them in the four main LLMs each week, and record whether your domain appears cited, in what position, and with what fragment. This generates a Share of Voice metric by question category.
Example of a corpus for a CDP company:
How long does it take to implement a CDP in a B2B company?
What native integrations should a CDP have for marketing teams?
How to synchronize CRM and CDP data without duplicating records?
What metrics to measure in the first 90 days of a CDP?
What is the real cost of maintaining a CDP in companies with more than 500 employees?
If you run those questions each week and your domain appears cited in 40% of the responses, you have a 40% Share of Voice. If it rises to 60% after optimizing content with Answer Capsules, you can justify the impact.
The second metric is traffic referred from AI domains. Some LLMs, like Perplexity, send direct traffic with UTM parameters. You can track it in Analytics and measure conversion. However, most citations do not generate a click; therefore, Share of Voice is more relevant than CTR.
The third metric is the impact on the pipeline. If your content is cited in AI responses during the buyer's research phase, you can track how many leads that reach sales mention having seen your brand in ChatGPT or Perplexity. This requires adding an explicit question to the contact form or the qualification call. It is not direct attribution, but it is a signal of assistance.
The goal is not to replace traditional SEO; it is to complement it. If your organic strategy generates 500 MQLs per month from Google and 80 from LLM citations, those 80 have a near-zero acquisition cost and higher quality, because the user already validated your authority before arriving at the site.
Frequently Asked Questions
Why do Answer Capsules work better in transactional B2B content than in generic educational content?
Transactional pages (comparisons, integrations, use cases) are at the bottom of the funnel and generate direct MQLs. If you structure those pages with extractable technical capsules (integration times, supported APIs, record limits, prerequisites), an LLM can cite them independently in specific responses. This not only increases the probability of citation, but it also improves conversion on the site itself because users from Zero-Click searches look for quick answers without beating around the bush. Generic educational content competes with a thousand sources, whereas well-structured transactional content has no direct competition.
How to measure GEO impact on the pipeline when Google Analytics does not differentiate traffic from AI Overviews?
The key metric is the Share of Voice in AI responses. You build a corpus of 30 to 50 questions relevant to your buyer persona, run them weekly in ChatGPT, Perplexity, Gemini, and Claude, and register whether your domain appears cited, in what position, and with what fragment. That generates a percentage of Share of Voice per question category. The second metric is the impact on the pipeline: you add an explicit question to the contact form or the qualification call to track how many leads mention having seen your brand in LLMs. It is not direct attribution, but it is a signal of assistance with a near-zero acquisition cost.
What is Information Gain and why does it prevent your content from being penalized as AI Slop?
Information Gain means providing content that does not exist in the model's training corpus. If your article repeats what is already on a thousand sites, the LLM has no incentive to cite you. But if you provide your own data (aggregated client metrics, internal benchmarks, technical comparisons with explicit methodology), the model has no alternative; it either cites you or it cannot answer. AI Slop dilutes the signal because thousands of AI-generated articles repeat the same structure without new data. That causes models to probabilistically penalize those domains in the RAG retrieval graph. Each article must include at least one unique element to maintain survival in the semantic index.
Sources
Related articles
ChatGPT Can Cost You a Sale Before the Click
Some sales are no longer lost on your website. ChatGPT can compare, reject and recommend before the click, leaving no visit, no abandoned cart and no trace in your dashboard.
How to turn your content into audio without setting up a studio
Turn any Studio article, social adaptation or free-editor text into natural audio. Own engine, curated voices, free samples and pay-per-word, right from the same button.
Don't publish every day. Build a system
Publishing daily out of fear of vanishing burns you out, blurs your brand and fills your channels with noise. The way out is a system: a few good ideas, one base piece a week and channel adaptation.
Found this useful? Share it with someone who needs it!